Order Entry Automation: End Triple Data Entry
Order entry automation guide: stop re-keying orders across CRM, ERP and WMS. Capture, validation, safe writes, exceptions and payback maths for two volumes.
AI Engineer, Viithiisys
The cost of re-keying, quantified
Re-keying cost is time per order multiplied by the number of systems that each need the same data typed in. A single order keyed into a CRM, an ERP and a WMS is typed three times, and each pass adds both minutes and a fresh chance of error.
There is no audited public benchmark for re-keying time that applies across industries, so this guide uses a stated model rather than a borrowed statistic. Replace the assumptions with your own stopwatch numbers.
What does triple data entry look like in practice?
A typical pattern: a customer emails a PDF purchase order. Someone creates or updates the opportunity in the CRM, someone else keys the sales order into the ERP, and the warehouse team retypes or corrects lines in the WMS when the pick release does not match what they were told.
Assume 4 minutes of keying per system for a ten-line order. That is 12 minutes per order, and the three copies drift: a unit of measure changes in one place, a ship-to address in another. The drift is usually the more expensive part, because it surfaces as a wrong shipment rather than a typo.
A worked example of drift: the ERP order says 10 cases of 12 units, but the warehouse operator, reading the PDF, keys 10 units into the WMS because the customer's layout labels the column "Qty". The pick is short by 108 units, the customer calls, and a reshipment is expedited. The 4 minutes saved by skipping a double-check cost far more than the keying itself, which is why the model below treats keying time as the floor of the cost, not the ceiling.
Where orders arrive: email, PDF, portal, phone
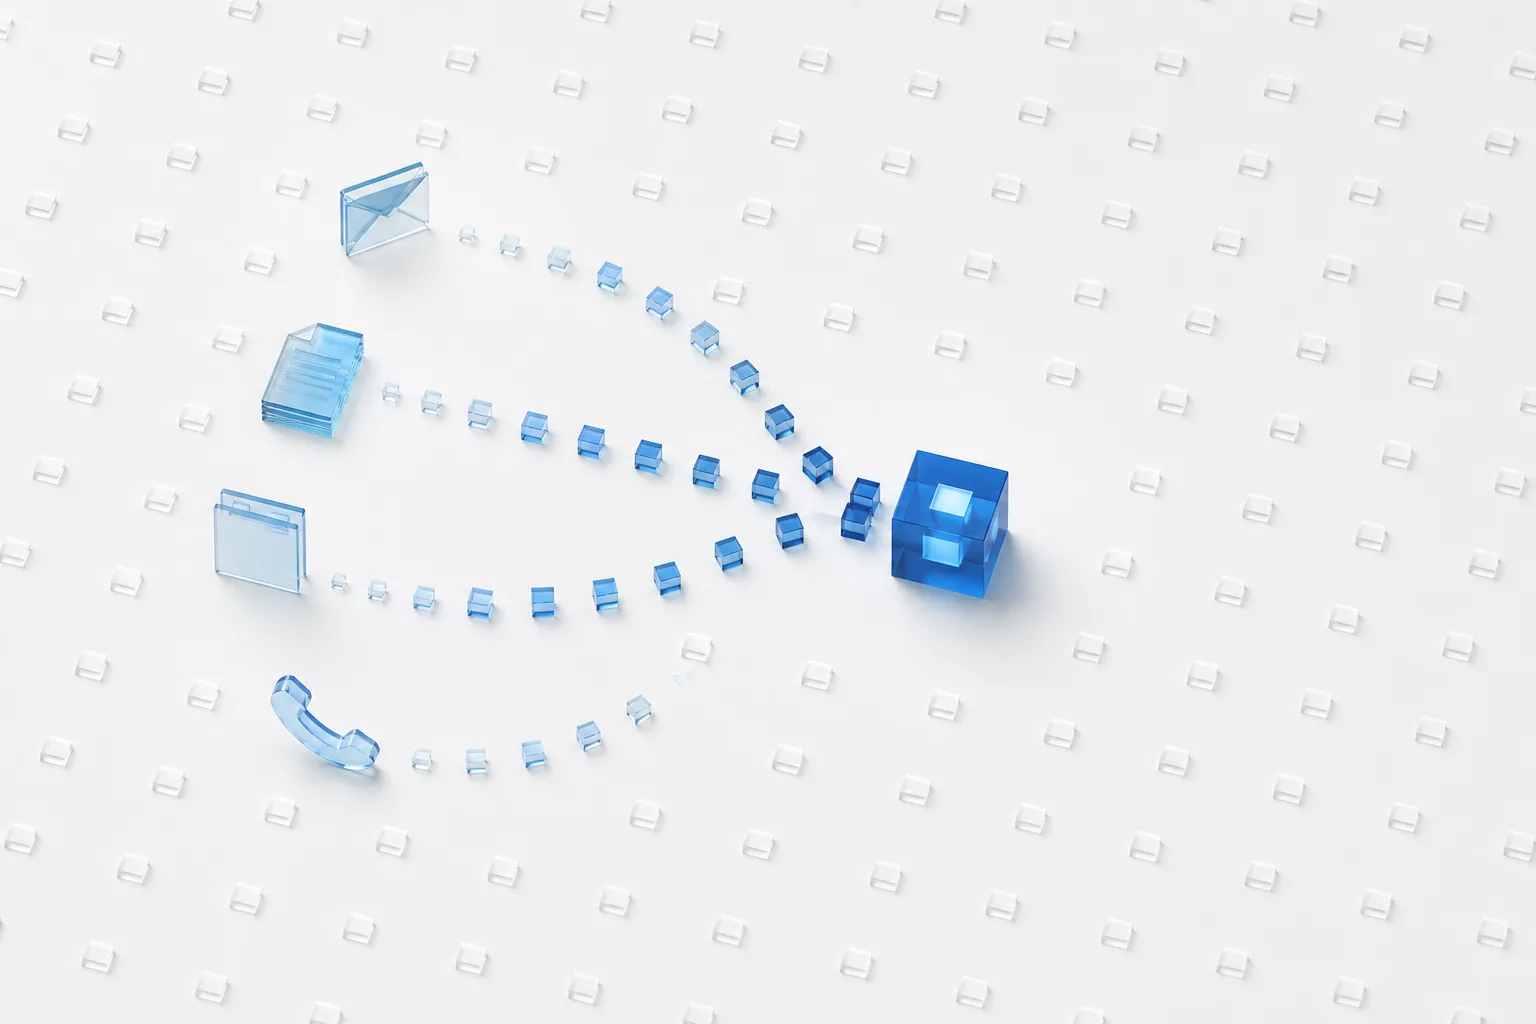
Orders reach a business through four main doors: email bodies and attachments, PDF or scanned purchase orders, customer portals and marketplaces, and phone or chat. Each needs a different capture method, so inventory your real mix before choosing tooling.
Which channel should you automate first?
Start with the channel that has the highest volume and the most repeatable format. For many distributors that is PDF purchase orders from a short list of large customers.
To inventory your mix, pull a month of orders and tag each by arrival channel and customer. Rank customers by order count; it is common for a handful of accounts to produce the majority of volume, and those accounts usually send the same layout every time. That ranking, not vendor enthusiasm, should decide your first build.
| Channel | Typical format | Capture method | Main risk |
|---|---|---|---|
| Email body | Free text, forwarded threads | LLM extraction | Ambiguous quantities and edits mid-thread |
| PDF / scan | Customer-specific PO layouts | Document AI plus validation | Layout changes, poor scan quality |
| Portal / marketplace | Structured export or API | Direct integration | Rate limits, schema changes |
| Phone / chat | Notes typed by staff | Structured entry form | Skipped mandatory fields |
Portals and APIs are the cheapest to automate because the data is already structured. Free-text email is the most flexible and the most error-prone, so it needs the strictest validation.
Extraction and validation layer
Extraction turns an unstructured order into fields; validation checks those fields against what your business already knows. Extraction alone is not automation. Validation is what lets you trust the output without a person reading every line.
How should extraction work for PDF and email orders?
Use a layout-aware document service for scanned and tabular PDFs. Amazon Textract's AnalyzeExpense API and Microsoft's Azure AI Document Intelligence both return line items with confidence scores, though their prebuilt models target invoices and receipts, so purchase orders usually need a custom model or an LLM pass.
For email bodies, an LLM with a fixed output schema works well. Anthropic's tool use documentation describes forcing structured JSON output, which keeps the result machine-checkable. Our document AI work follows this pattern: model proposes, deterministic code verifies.
What should validation check?
Run every extracted order through rules the model cannot overrule:
- Customer matches an account, and the ship-to belongs to that account.
- Every SKU exists, including customer-specific part numbers mapped to yours.
- Price and unit of measure fall within the contract or an agreed tolerance.
- Line totals add up to the stated order total.
Confidence scores from the extraction service are an input to these rules, not a substitute. A common design sets a per-field threshold, for example sending any quantity or price field below your chosen cutoff to review even when every other rule passes. Tune the cutoff against your shadow-mode data rather than guessing.
The extraction model is the easy part; the validation rules are what make an order safe to post without a human reading it.
Writing to ERP, WMS and CRM without collisions
Write once, from one place, with an idempotency key. The automation layer holds the validated order, creates the sales order in the ERP, and lets that system propagate to the WMS and CRM, rather than three parallel writes that can disagree.
Which system owns which field?
Decide ownership before building. A common split is the ERP owning customer, pricing and order status, the WMS owning pick and pack status, and the CRM owning the relationship and pipeline.
Anything that crosses a boundary flows one way, from the owner outward. Two-way sync on the same field is where collisions start, so avoid it unless you have a written conflict rule.
How do you stop duplicate orders?
Retries are normal: a timeout does not tell you whether the ERP created the order. Generate a deterministic key from customer, PO number and a content hash, and check it before every create.
The pattern is the same one payment APIs use; Stripe's idempotent requests documentation explains it clearly. Store the key with the ERP order number so a replay returns the existing record instead of a second one. Our AI integration projects treat this as non-negotiable, because a duplicate order is a duplicate shipment.
One trade-off to spell out: including the content hash means a customer's legitimately revised PO, with the same PO number but changed quantities, produces a new key and a new order. Handle that deliberately by flagging same-PO-number, different-content arrivals to a person as a probable amendment, rather than posting a second order or silently ignoring the change.
Exception handling design
Exceptions are not a failure of the system; they are a designed output of it. A good design decides in advance which problems get auto-resolved, which go to a person, and how fast that person sees them.
What goes to a human, and how?
Route by cause, not by a single "needs review" bucket. A missing SKU mapping goes to master-data staff, a price mismatch goes to sales, and an unreadable scan goes back to the customer with a templated request.
Each queue item should show the original document beside the extracted fields, with the failing rule highlighted. The reviewer fixes one field and approves, instead of rekeying the order.
How do you keep the exception rate falling?
Log every correction. A repeated fix, such as a customer who always writes "EA" for "each", becomes a mapping rule, so the same exception does not return.
Track the touchless rate (orders posted with no human action) and the exception rate per customer. A customer with a persistently high rate usually needs a conversation about format, which is a business fix rather than a technical one.
Payback for 500 / 2,000 orders a month
Payback is hours removed multiplied by your loaded labour rate, set against build and run cost. The inputs below are assumptions for illustration, not measured results, and the build cost is scoped per project after discovery.
What do the hours look like at each volume?
Using the earlier model of 12 minutes of keying per order across three systems, and assuming 70% of orders post touchless with the rest needing 3 minutes of review:
| Monthly orders | Keying hours today | Hours after automation | Hours saved |
|---|---|---|---|
| 500 | 100 | 17.5 | 82.5 |
| 2,000 | 400 | 70 | 330 |
Multiply hours saved by your own loaded hourly cost to get the monthly saving, then divide the build and run cost by that figure to get months to payback.
What does the model leave out?
It excludes error cost: credit notes, returns and expedited reshipments from wrong orders. Those are often larger than keying time but vary too much by business to estimate without your data.
It also assumes the touchless rate holds. At 500 orders a month, a small customer base with fixed formats can reach it quickly. At 2,000, long-tail customers with unique layouts drag it down, so start with the top customers by volume.
Rollout without stopping the floor
Run the automation in shadow mode first, comparing its output with what your team keys, then move one customer or channel live at a time. The order desk never stops, and each step produces evidence before the next.
What does a safe rollout sequence look like?
- Shadow mode. The system processes real orders but posts nothing. Compare its output against the human-entered order and measure field-level agreement.
- Assisted mode. It pre-fills the ERP order screen and a person approves every order.
- Selective touchless. Orders that pass all validation for approved customers post directly; everything else queues.
- Expansion. Add channels and customers as the correction log shrinks.
Keep a manual path and a kill switch throughout. If the ERP is down or extraction misbehaves, orders queue rather than vanish.
Viithiisys has shipped software since 2007, across 500+ projects for clients including Paytm, Snapdeal, IKEA, Nestle, Shiprocket and Vikram Solar, and the integration lesson that repeats is that the cutover plan matters as much as the code. Our AI workflow automation team works from Mohali with a Canadian office in Markham, Ontario, serving US, UK and Canadian operations teams. You can browse the wider solutions we build for operations teams.
If you suspect your order flow is being retyped more than it should be, the free workflow audit maps where the re-keying happens and which channel to automate first.
FAQ
- What is order entry automation?
- Order entry automation is software that captures incoming customer orders from email, PDF, EDI, portals or phone notes, extracts the fields, validates them against master data, and creates the sales order in your ERP without anyone re-keying it. People handle only the orders the system cannot confidently resolve.
- How do I eliminate double data entry between ERP, WMS and CRM?
- Pick one system as the source of truth for each field, capture the order once, and write to the other systems through APIs using an idempotency key. Downstream systems then receive the record rather than a human retyping it, which removes both the labour and the mismatch errors.
- How accurate does AI extraction need to be before it is safe to use?
- Accuracy matters less than knowing when you are wrong. Set confidence thresholds per field, validate against customer, SKU and price master data, and send anything below threshold to a review queue. Start with every order reviewed, then relax the check field by field as the error data justifies it.
- How long does it take to roll out sales order automation?
- It depends on the number of order channels, customer formats and ERP integration complexity, so it is scoped after a discovery call rather than quoted blind. A sensible pattern is shadow mode first, then one customer or channel live, then expansion, so the order desk keeps working throughout.